Autopilot for Coding Agents Without Handing Over Your Homelab
This article is fully human written. No LLM was used to generate any of the text.
Do you work on your homelab with autonomous coding agents?
I would bet the answer is yes, because this is the era of Agentic AI, where nobody is writing code by hand anymore (or blog posts, sigh).
The Problem
Well, actually, there are several problems with working on your homelab with autonomous coding agents:
- Providers can record your prompts and use your homelab source code to train their models.
- Agents can send your personal data and access keys to 3rd parties.
- A lot of homelabs (mine included) have self-hosted APIs exposed with sub-optimal authn/authz as they do not expect untrusted actors inside the internal network.
- Coding agents can tinker with your homelab and break it.
- Agents can use unlimited amounts of tokens, leading to huge spend.

The Solution
We are going to create a Gitops-based isolated dev environment for our coding agent.
The solution consists of:
- Dedicated dev VM. The agent runs inside this VM. Personal repositories are never cloned to this VM and it’s blocked from accessing the homelab network via network policies.
- Dedicated k8s cluster with dedicated dev namespaces.
- Dedicated gitops repo scoped to the dedicated k8s cluster. Commits in this repo act as an audit log of changes the agent made.
- AI gateway for rate limiting token usage and providing an audit log of LLM calls made by the agent. A grafana dashboard is used to display live LLM usage metrics exposed by the gateway.

Together, these prevent data exfiltration and unauthorized API usage, alongside neat observability.
Disclaimer: this solution is great for me. I already develop on VMs over ssh, use ArgoCD to deploy software, and expose services to my home network via K8s Gateway API.
Building The Setup
My homelab is built around Kubernetes so I’m going to build the solution around it.
Dedicated (KubeVirt) Dev VM
A debian 13 VM is provisioned with KubeVirt. We block access to internal homelab subnets with a network policy attached to the VM pod.
apiVersion: kubevirt.io/v1
kind: VirtualMachine
metadata:
  name: agent-sandbox
  namespace: workstation
spec:
  running: true
  template:
    spec:
      domain:
        cpu:
          cores: 4
          model: host-passthrough
        devices:
          disks:
            - disk:
                bus: virtio
              name: bootdisk
            - cdrom:
                bus: sata
                readonly: true
              name: cloudinitdisk
          interfaces:
            - masquerade: {}
              name: default
        machine:
          type: q35
        resources:
          requests:
            memory: 8G
      networks:
        - name: default
          pod: {}
      volumes:
        - name: bootdisk
          persistentVolumeClaim:
            claimName: agent-sandbox # created by a KubeVirt DataVolume.
        - name: cloudinitdisk
          cloudInitNoCloud:
            userData: |
              #cloud-config
# ssh key + qemu-guest-agent provisioningapiVersion: networking.k8s.io/v1
kind: NetworkPolicy
metadata:
name: agent-sandbox-egress
namespace: workstation
spec:
podSelector:
matchLabels:
vm.kubevirt.io/name: agent-sandbox
policyTypes:
- Egress
egress:
- to:
- namespaceSelector:
matchLabels:
kubernetes.io/metadata.name: kube-system
podSelector:
matchLabels:
k8s-app: kube-dns
ports:
- protocol: UDP
port: 53
- protocol: TCP
port: 53
# Public internet, excluding the cluster's own pod/service subnets
# and other private ranges.
- to:
- ipBlock:
cidr: 0.0.0.0/0
except:
- 10.0.0.0/8
- 172.16.0.0/12
- 192.168.0.0/16
- 100.64.0.0/10
# agent-sandbox-cluster API server
- to:
- ipBlock:
cidr: 10.130.0.12/32
ports:
- protocol: TCP
port: 6443
- to:
# ai.lab.linuxdweller.com (AI gateway)
- ipBlock:
cidr: 10.130.0.11/32
# argo.management.linuxdweller.com (ArgoCD API server)
- ipBlock:
cidr: 10.130.0.2/32
ports:
- protocol: TCP
port: 443AI Gateway
Any AI gateway which has rate limiting and exposes Prometheus metrics should do the job.
I chose to use Agent Router (formerly Envoy AI Gateway) as I already use Envoy Gateway controller in my clusters. It is fully configurable with CRDs and owned by a neutral foundation (Agentic AI Foundation).
I have a two-part series for setting it up from scratch. Here is part one (installation) and here is part two (configuration).
Dedicated GitOps Repo
Configure a dedicated gitops repository which is connected only to our dedicated k8s cluster.
The agent should have a fine-grained access token scoped to this repo so it can push commits only to it.
An ApplicationSet watches this repo and generates an application from each top level directory. The application is installed to a namespace named after the directory.
apiVersion: argoproj.io/v1alpha1
kind: ApplicationSet
metadata:
  name: agent-sandbox
  namespace: argocd
spec:
  goTemplate: true
  goTemplateOptions:
    - missingkey=error
  generators:
    - git:
        repoURL: https://github.com/linuxdweller/agent-sandbox-gitops
        revision: HEAD
        directories:
          - path: "*"
  template:
    metadata:
      name: "{{ .path.basenameNormalized }}"
    spec:
      project: agent-sandbox
      source:
        repoURL: https://github.com/linuxdweller/agent-sandbox-gitops
        targetRevision: HEAD
        path: "{{ .path.path }}"
      destination:
        name: agent-sandbox/agent-sandbox-cluster
        namespace: "{{ .path.basenameNormalized }}"
      syncPolicy:
        automated:
          selfHeal: true
          prune: true
        syncOptions:
          - CreateNamespace=true
          - ServerSideApply=true
        retry:
          limit: -1
          backoff:
            duration: 15s
            factor: 2
            maxDuration: 60s
The AppProject is scoped to deploy specific resources only to specific namespaces. We prohibit creating cluster scoped resources (such as ClusterRole) to prevent potential access to other namespaces.
apiVersion: argoproj.io/v1alpha1
kind: AppProject
metadata:
  name: agent-sandbox
  namespace: argocd
  finalizers:
    - resources-finalizer.argocd.argoproj.io
spec:
  description: >-
    Sandbox project for content pushed by the agent-sandbox VM to
    agent-sandbox-gitops.
  sourceRepos:
    - https://github.com/linuxdweller/agent-sandbox-gitops
  destinations:
    - name: agent-sandbox/agent-sandbox-cluster
      namespace: litellm
  clusterResourceWhitelist:
    - group: external-secrets.io
      kind: ClusterSecretStore
  namespaceResourceBlacklist:
    - group: ""
      kind: Secret
    - group: ""
      kind: ServiceAccount
    - group: ""
      kind: ResourceQuota
    - group: ""
      kind: LimitRange
    - group: rbac.authorization.k8s.io
      kind: Role
    - group: rbac.authorization.k8s.io
      kind: RoleBinding
    - group: networking.k8s.io
      kind: NetworkPolicy
    - group: argoproj.io
      kind: Application
    - group: argoproj.io
      kind: AppProject
    - group: argoproj.io
      kind: ApplicationSet
  roles:
    - name: sync-role
      policies:
        - p, proj:agent-sandbox:sync-role, applications, sync, agent-sandbox/litellm, allow
        - p, proj:agent-sandbox:sync-role, applications, get, agent-sandbox/litellm, allow
Segregating the agent to specific dev namespaces prevents it from accessing the rest of our homelab services which live outside the cluster.
The AppProject includes a role with read/refresh/sync permissions which our agent will use to trigger those actions manually.
Dedicated K8s Cluster
We create a dedicated K8s cluster and connect it to ArgoCD. The manifests for that are omitted for brevity since this process is different for everyone.
In case pods can reach your homelab subnets, it is important to create a network policy to prevent that in each namespace the agent can deploy to via Argo:
apiVersion: networking.k8s.io/v1
kind: NetworkPolicy
metadata:
  name: litellm-egress
  namespace: litellm # Dev namespace.
spec:
  podSelector: {}
  policyTypes:
    - Egress
  egress:
    - to:
        - namespaceSelector:
            matchLabels:
              kubernetes.io/metadata.name: kube-system
          podSelector:
            matchLabels:
              k8s-app: kube-dns
      ports:
        - protocol: UDP
          port: 53
        - protocol: TCP
          port: 53
    # Public internet, same shape as the VM's policy.
    - to:
        - ipBlock:
            cidr: 0.0.0.0/0
            except:
              - 10.0.0.0/8
              - 172.16.0.0/12
              - 192.168.0.0/16
              - 100.64.0.0/10
Read-Only Service Account
While mutating actions (creating resources) happen through git and Argo, querying the live state of the cluster is done with a read-only SA.
It is equipped with permissions to:
- Read-only for all resources in the dev namespaces.
portforwardanddeleteonpodsandjobsin the dev namespaces.- Read-only for
namespacesandnodesresources.
apiVersion: v1
kind: ServiceAccount
metadata:
  name: agent-sandbox-readonly
  namespace: agent-sandbox
---
apiVersion: v1
kind: Secret
metadata:
  name: agent-sandbox-readonly-token
  namespace: agent-sandbox
  annotations:
    kubernetes.io/service-account.name: agent-sandbox-readonly
type: kubernetes.io/service-account-tokenapiVersion: rbac.authorization.k8s.io/v1
kind: Role
metadata:
name: agent-sandbox-litellm-readonly
namespace: litellm
rules:
- apiGroups: ["*"]
resources: ["*"]
verbs: [get, list, watch]
- apiGroups: [""]
resources: [pods/portforward]
verbs: [create]
- apiGroups: [""]
resources: [pods]
verbs: [delete]
- apiGroups: [batch]
resources: [jobs]
verbs: [delete]
---
apiVersion: rbac.authorization.k8s.io/v1
kind: RoleBinding
metadata:
name: agent-sandbox-litellm-readonly
namespace: litellm
subjects:
- kind: ServiceAccount
name: agent-sandbox-readonly
namespace: agent-sandbox
roleRef:
apiGroup: rbac.authorization.k8s.io
kind: Role
name: agent-sandbox-litellm-readonly
---
apiVersion: rbac.authorization.k8s.io/v1
kind: ClusterRole
metadata:
name: agent-sandbox-readonly-nodes
rules:
- apiGroups: [""]
resources: [nodes, namespaces]
verbs: [get, list, watch]
---
apiVersion: rbac.authorization.k8s.io/v1
kind: ClusterRoleBinding
metadata:
name: agent-sandbox-readonly-nodes
subjects:
- kind: ServiceAccount
name: agent-sandbox-readonly
namespace: agent-sandbox
roleRef:
apiGroup: rbac.authorization.k8s.io
kind: ClusterRole
name: agent-sandbox-readonly-nodesThis role is super useful to let our coding agent actually see what is going on in the cluster and fix things when they break.
Result
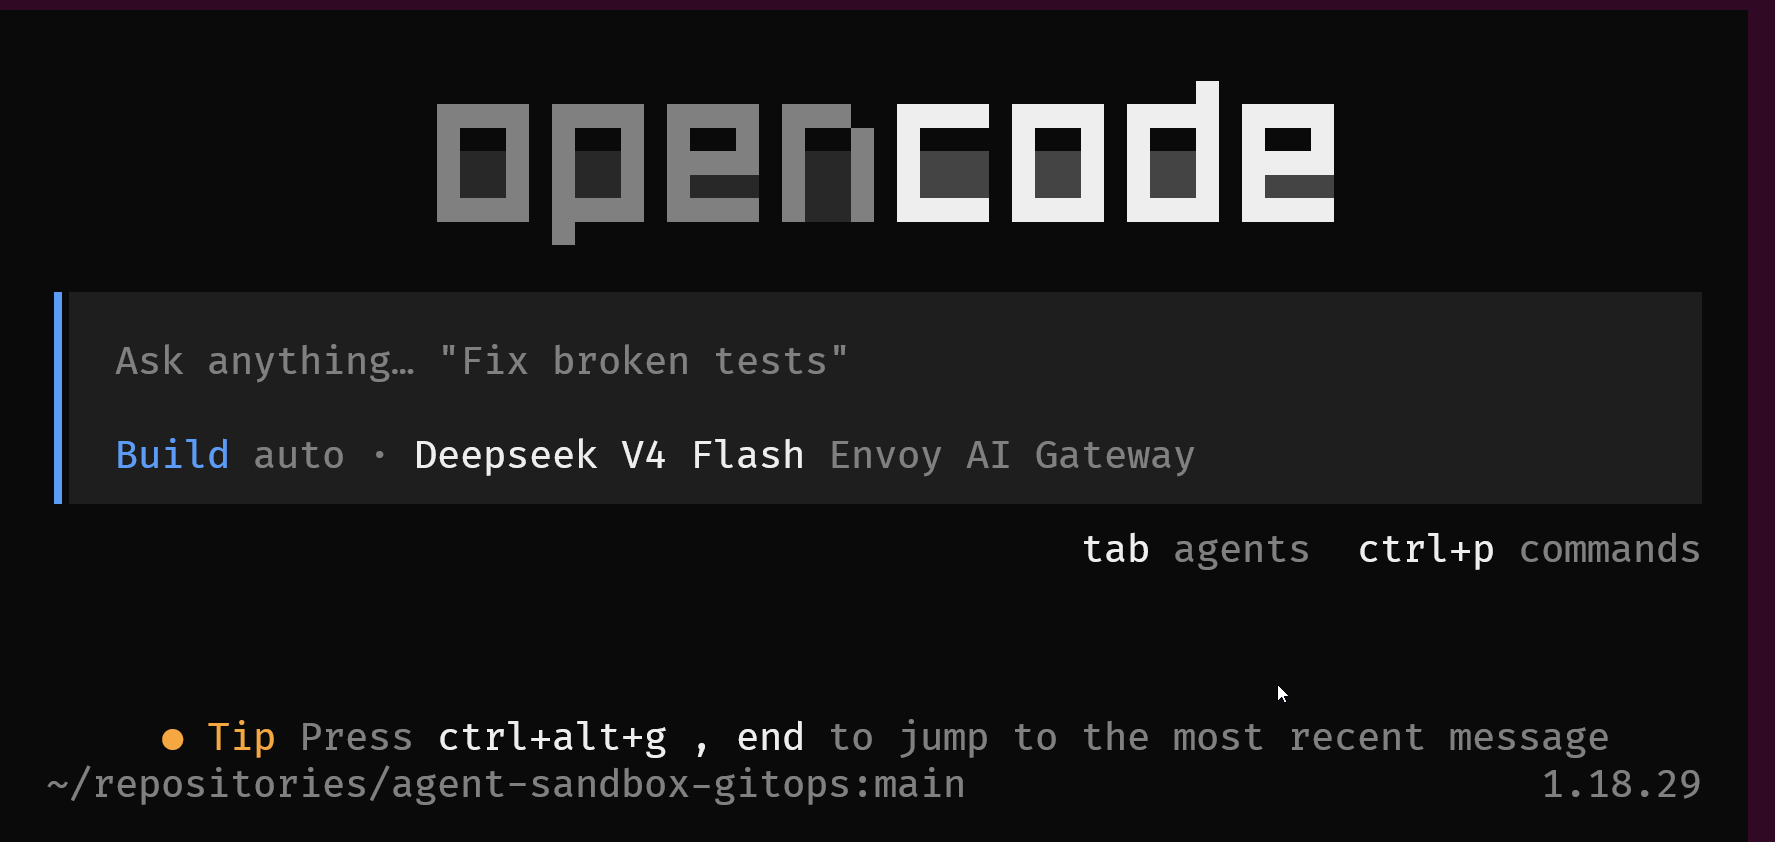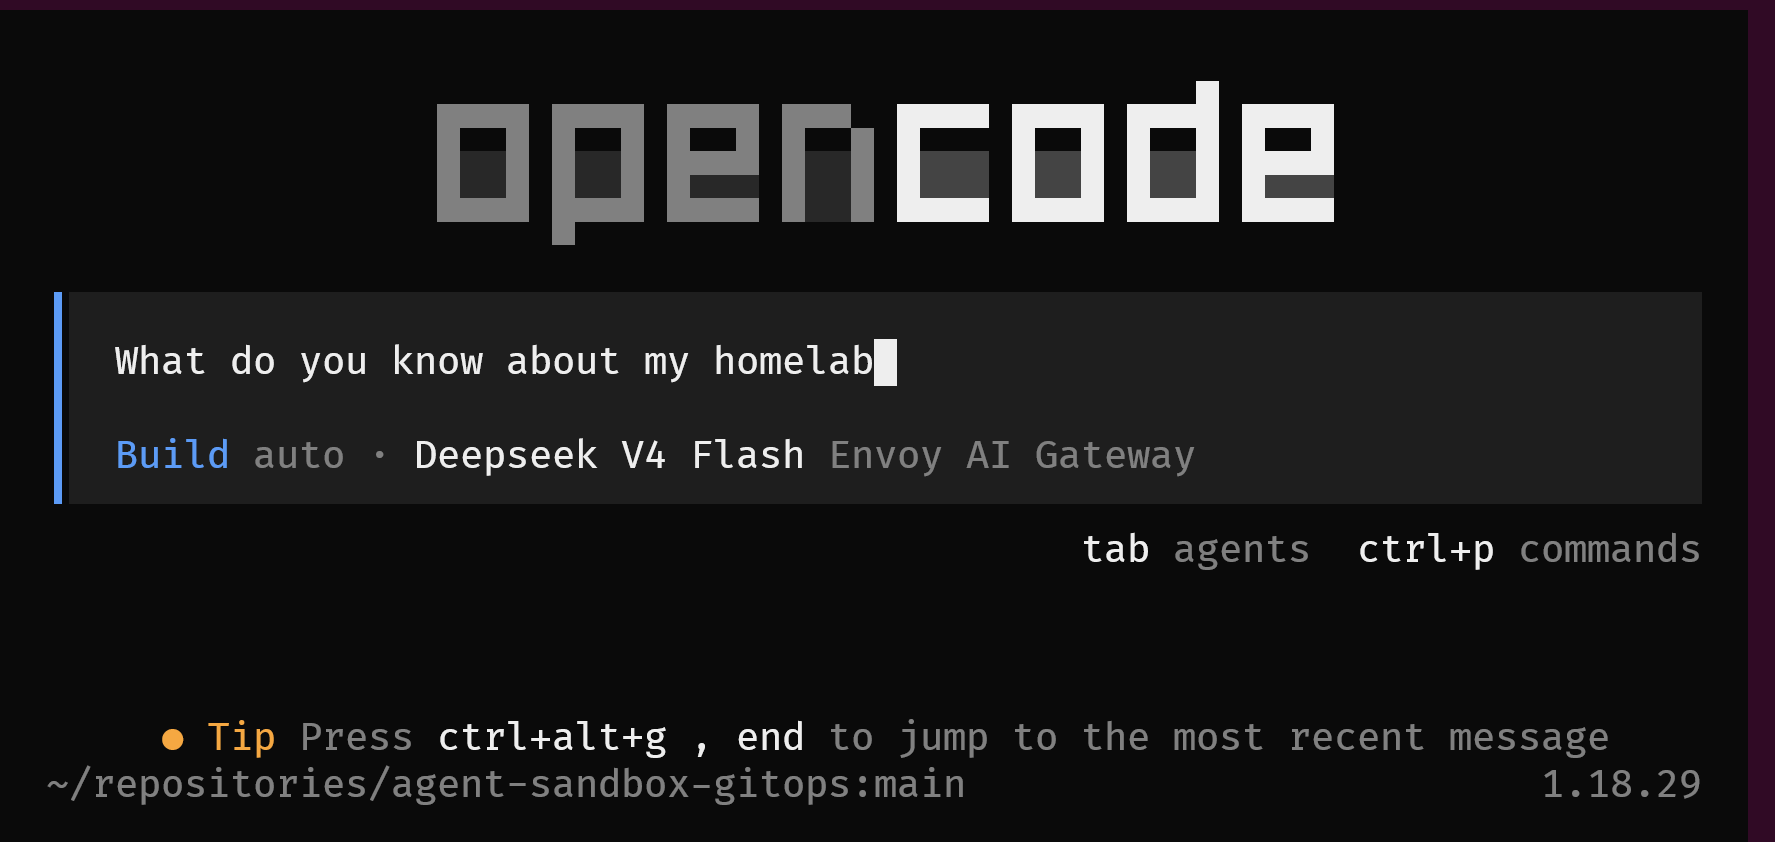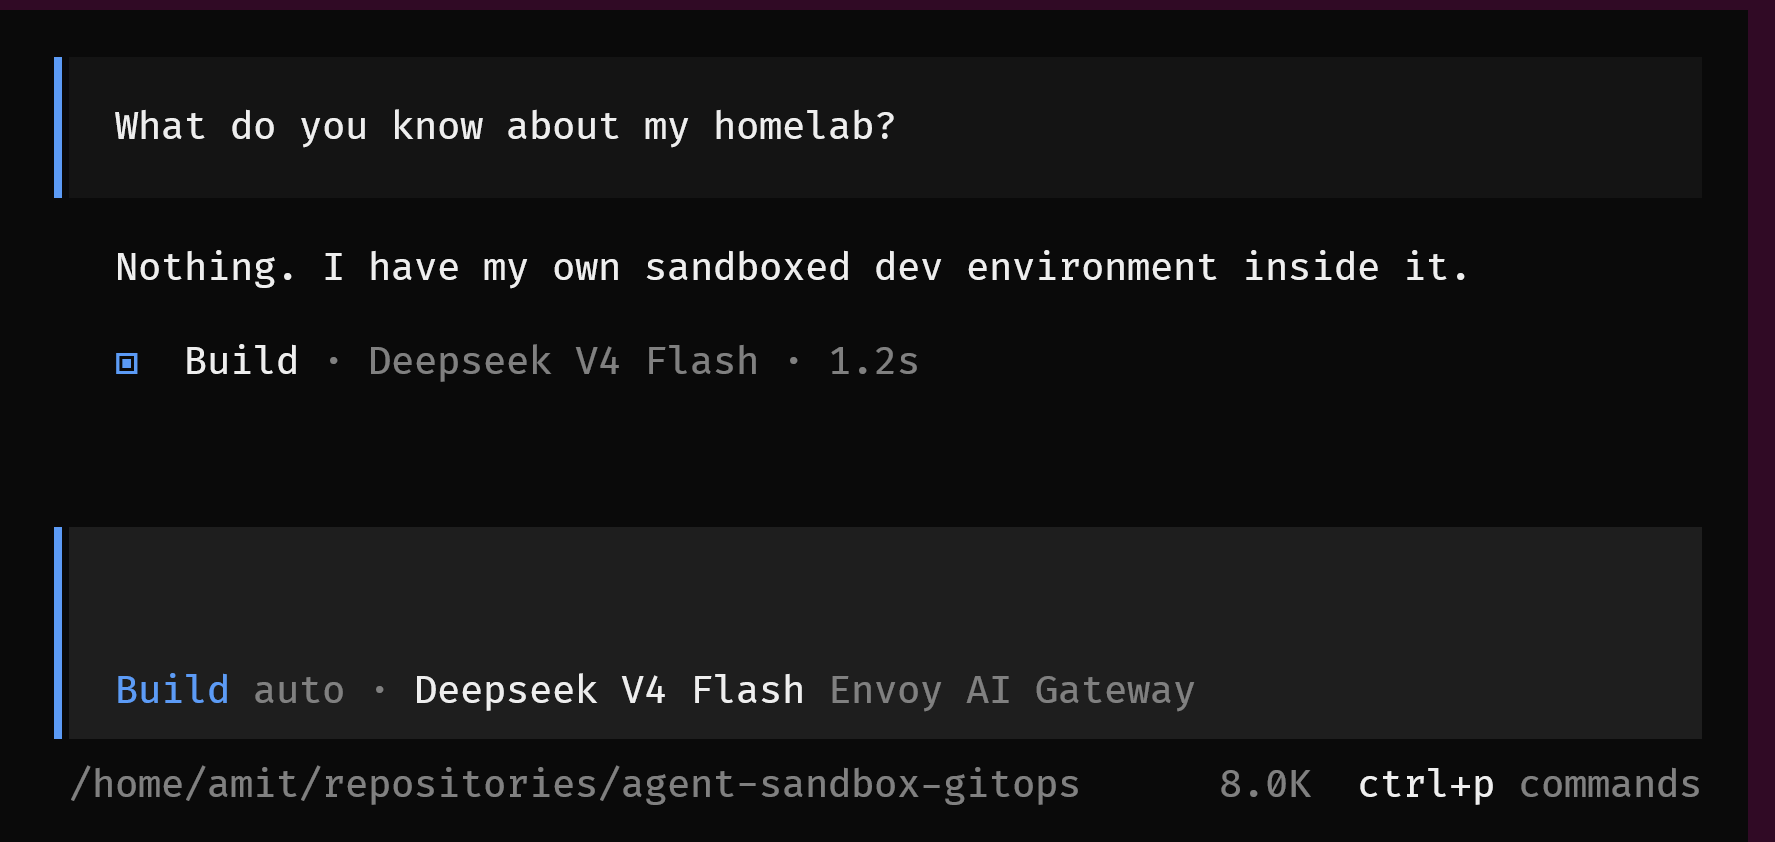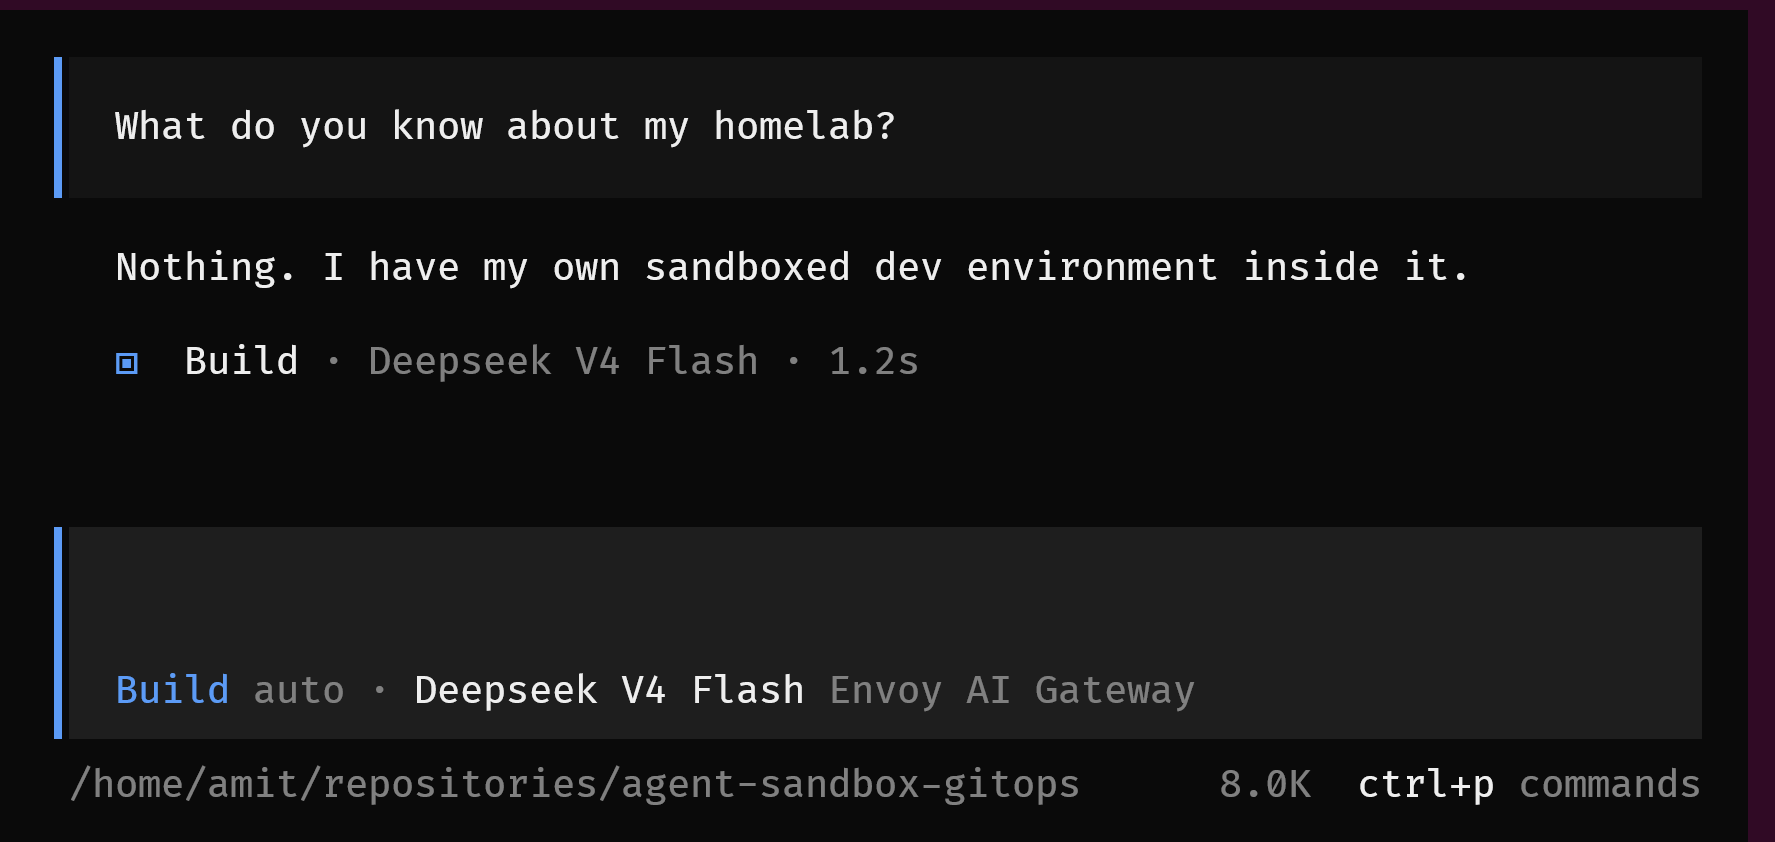
The result is a segregated VM which can only deploy to a segregated K8s cluster:
Autonomous coding agents can run without fear of them breaking things or leaking sensitive information to the outside world.
In my book of homelabbing, this is a huge win.
Tradeoffs
With current hardware prices this solution is very hard to justify.
Running a dev VM, K8s cluster, and Prometheus+Grafana just for local development is not cheap. It requires significant memory, cpu and storage which mostly sit idle and can’t easily scale down.
For me, the only reason this makes sense financially is that I have a lot of extra hardware sitting idle. My homelab rarely goes above 30% memory/cpu usage.
Limitations
This solution is still severely lacking. Coding agents running in this sandboxed VM are unable to:
- Access my “real” k8s clusters, where I actually deploy all my things and work regularly.
- Access Prometheus metrics and OTel logs and traces.
- Access shared storage (I use Ceph) and routers/switches in my home network.
Perhaps the next step would be a just-in-time permission system with fine-grained roles for every part of my homelab.
For now though I prefer waiting for the community to settle on tooling for agent permissions before I join everyone else and build my own.